Hi,
I have created a CSV endpoint to create CSV files for, in my case, organisational data that is to be sent to two different recipients in slightly different formats.
I created two different endpoints with different target directories, and two different execution jobs, in hope to be able to “assign” the files that I wanted to produce to different schedules and target folders.
I found out that this was not the case. All files get written to both my directories at the same time regardless of which of the endpoints I execute and there are no settings to change that.
The results look like this:
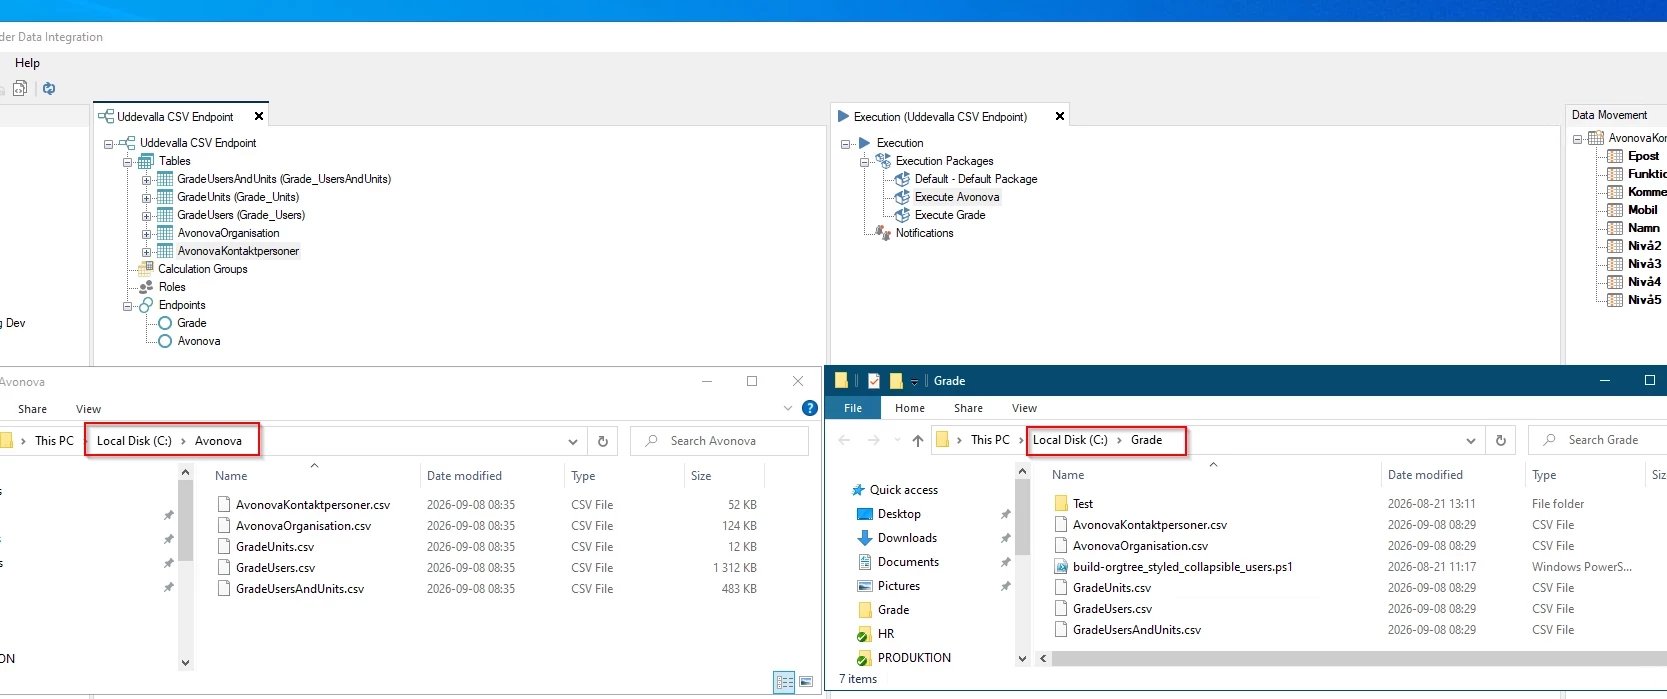
What would be nice, since each “table” in the endpoint will end up as a separate file anyway, would be if I could assign tables to separate endpoints so that it would be easier for our integration engine to pick up the relevant group of files from separate target folders.
This would also be safer since I then also can set different security levels on the target folders for outside access depending on the produced data. The scheduling would also be more flexible since, in my example, I want to produce the files for the Grade system once a day but the files for the Avonova system only need to be produced once a month.
To not risk overwriting already produced files it would also be great if there was a way to set a unique filename, based on datetime at the time when the files are produced. I think that there is already a suggestion for this in here.
I know that I can create another endpoint to separate this but since we in the future will have a plethora of different consumers of our data, it will also lead to a whole bunch of endpoints doing the same thing which feels a bit excessive.
Adding these features would make the CSV endpoint much more flexible.
